這段時間國產大模型deepseek受到廣泛關注,deepseek也開源了他們模型的引數,在huggingface上,提供了原始模型和經過不同程度蒸餾的模型
因為好奇,手邊剛好也有之前白嫖的阿里雲的伺服器,就嘗試一下本地部署的過程
本文簡單介紹一下部署的過程,也提供一個gradio的示例,進行模型的使用
1、白嫖阿里雲伺服器
免費試用,可以選擇互動式建模進行試用。
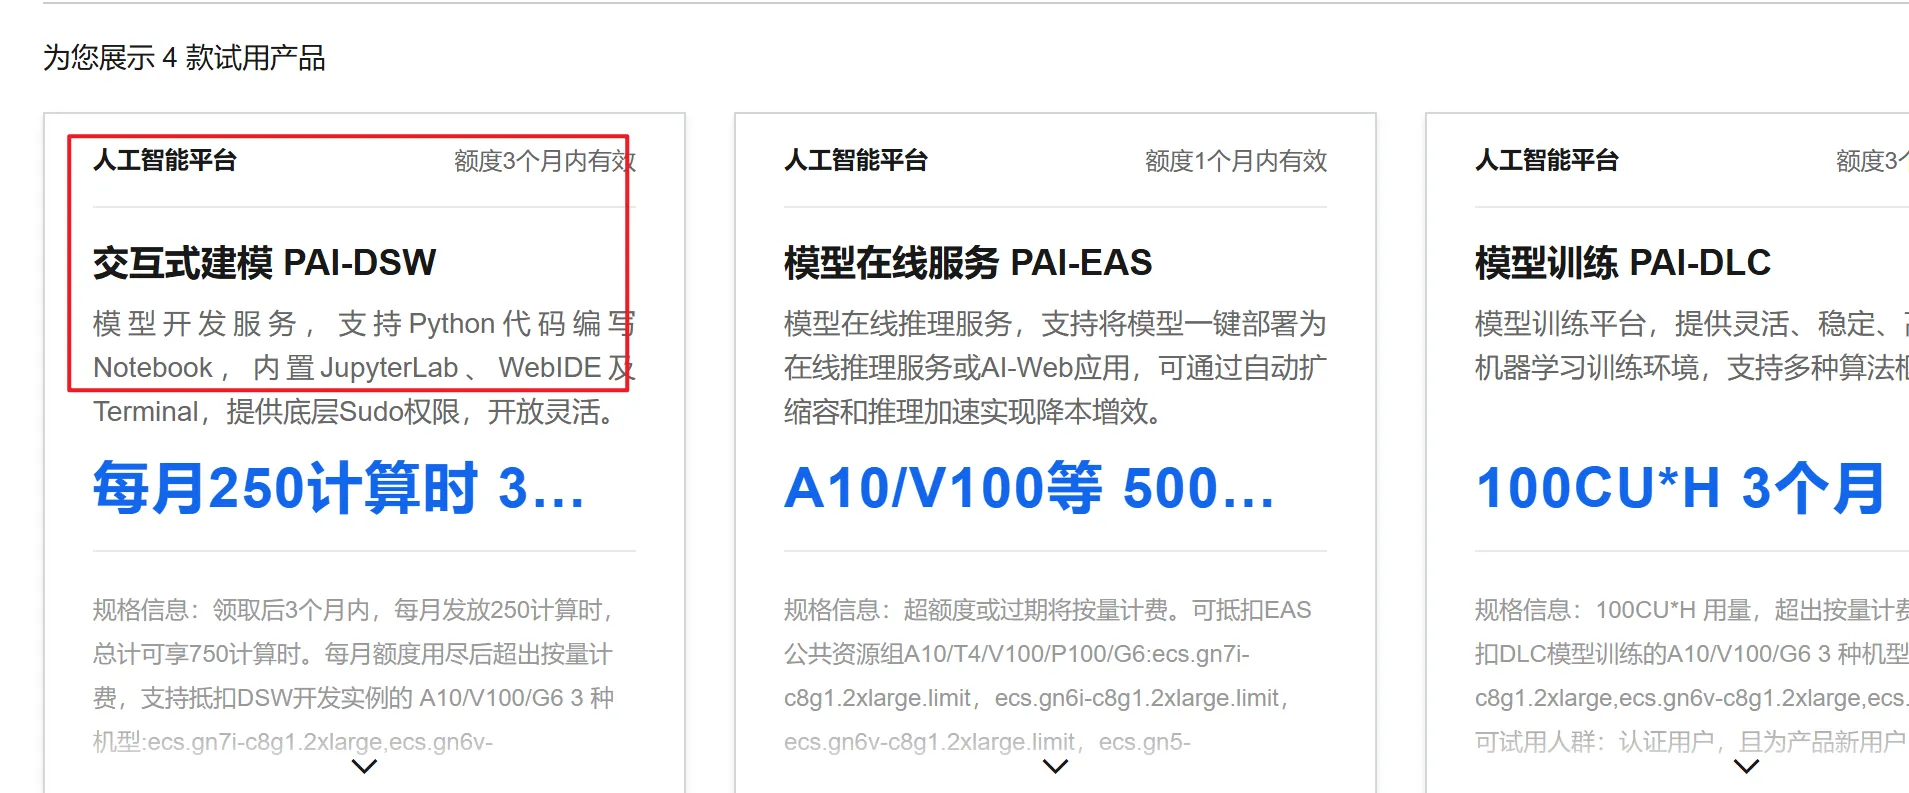
註冊阿里雲賬號並選擇試用即可
2、模型下載和載入測試
2.1、環境搭建
首先在阿里雲建立一個例項
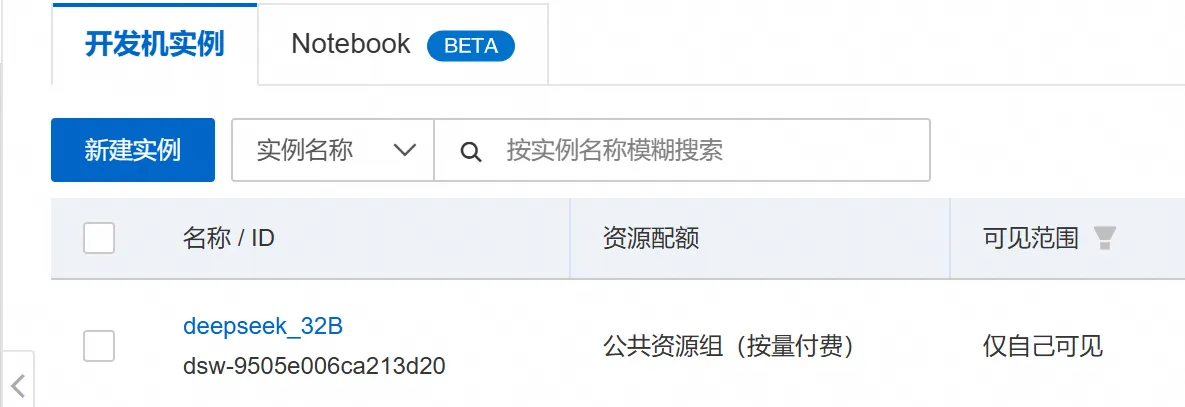
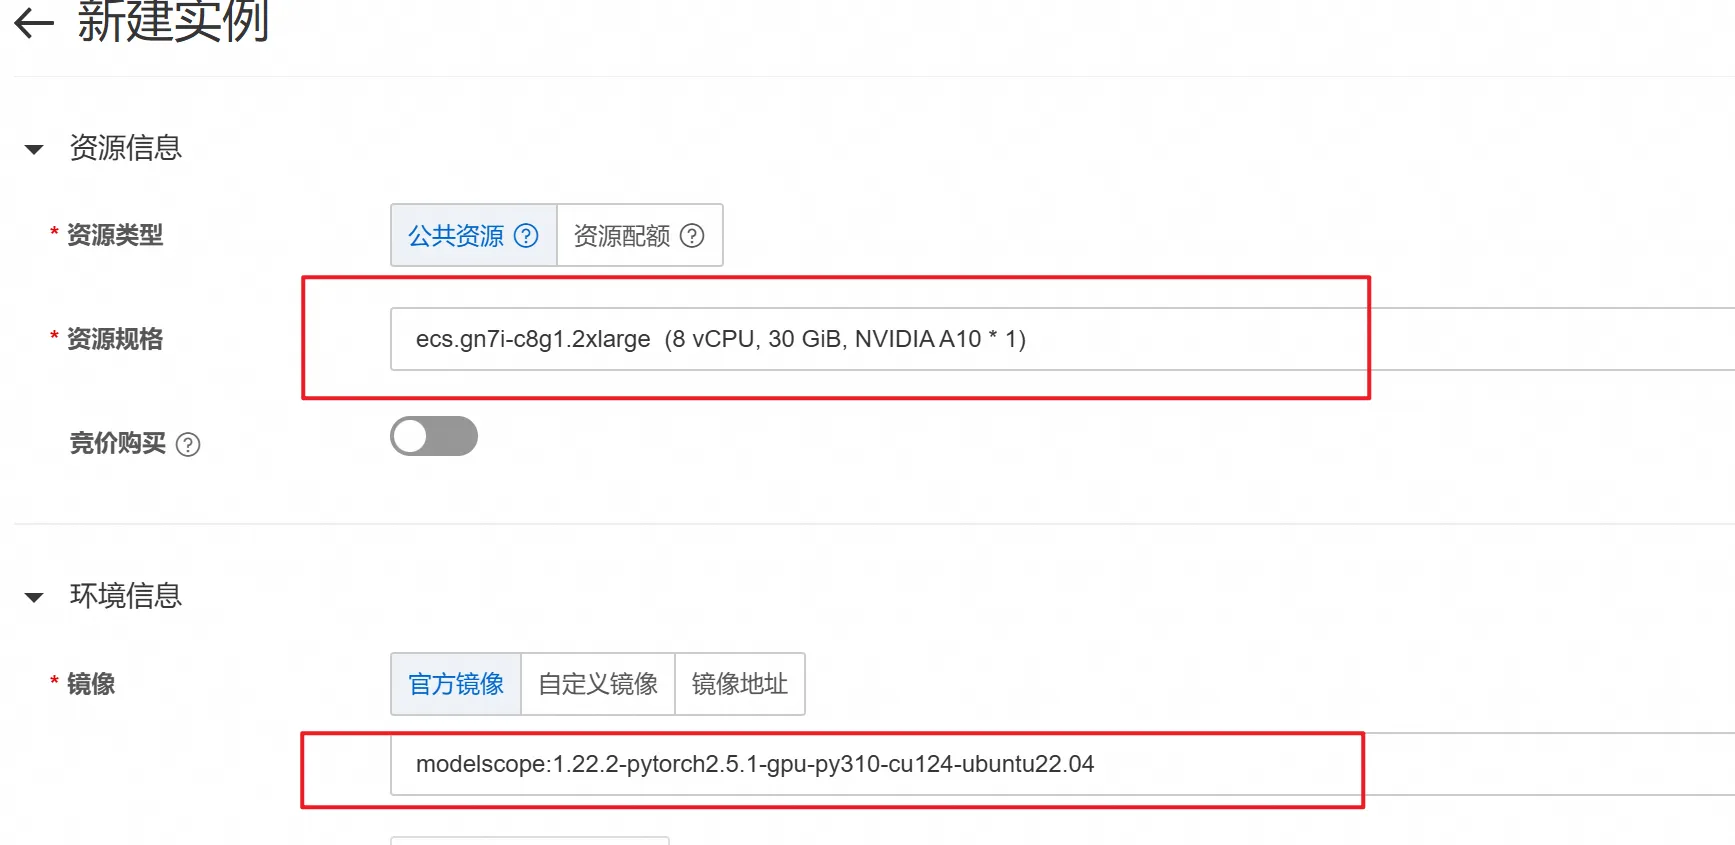
然後選擇選擇A10的GPU和圖中所示的映象
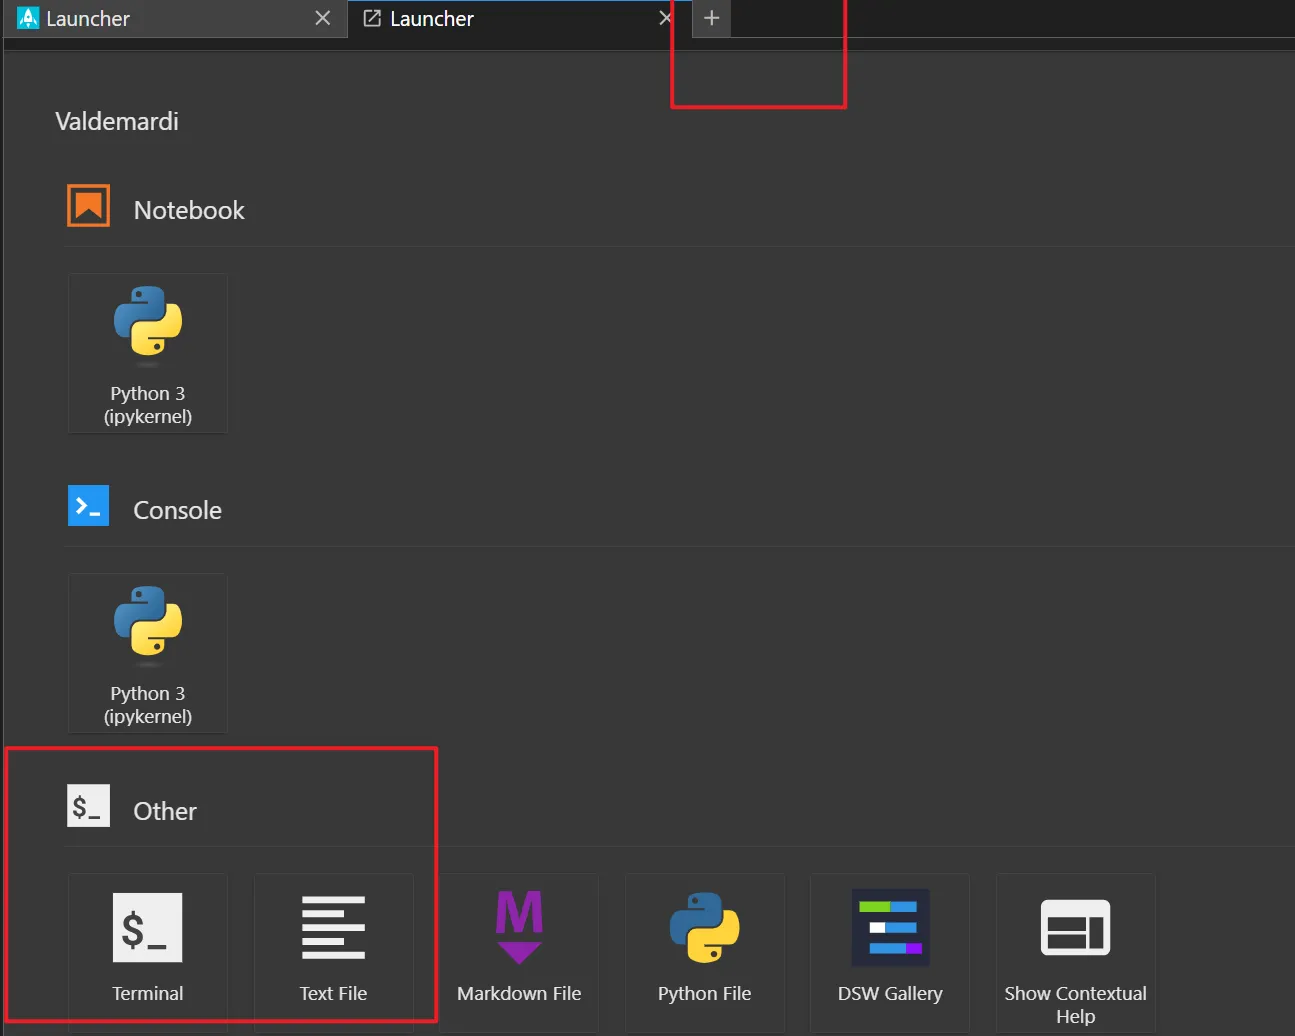
之後等待例項建立完成,進入例項環境,點選右上方加號,進入命令列
2.1、模型下載與測試
在命令列進行模型下載與測試
1、設定Hugging Face映象源
export HF_ENDPOINT=https://hf-mirror.com2、下載DeepSeek-R1 32B模型
huggingface-cli download Valdemardi/DeepSeek-R1-Distill-Qwen-32B-AWQ --cache-dir /mnt/workspace/Valdemardi/DeepSeek-R1-Distill-Qwen-32B-AWQ3、測試模型是否能載入成功
vllm serve Valdemardi/DeepSeek-R1-Distill-Qwen-32B-AWQ --quantization awq_marlin --max-model-len 1024 --max-num-batched-tokens 2048 --max-num-seqs 1 --tensor-parallel-size 1 --port 8003 --enforce-eager --gpu_memory_utilization=0.90 --enable-chunked-prefill相關引數說明: quantization awq_marlin:啟用AWQ量化,顯著降低視訊記憶體佔用。 max-model-len 1024:設定最大序列長度為1024個token,適用於大部分NLP任務。 max-num-batched-tokens 2048:設定批次處理的token數為512,平衡處理速度和視訊記憶體佔用。 max-num-seqs 1:設定同時處理的序列數為1,避免多序列處理帶來的視訊記憶體碎片。 tensor-parallel-size 1:禁用 tensor 並行,最大化利用視訊記憶體。 port 8003:設定服務監聽埠為8003。 enforce-eager:啟用 eager 模式,加快推理速度。 gpu_memory_utilization 0.90:設定視訊記憶體使用率為98%,儘可能多地利用視訊記憶體。 enable-chunked-prefill:啟用分塊預填充,減少視訊記憶體碎片。
3、gradio互動
使用gradio載入vllm推理模型,進行視覺化互動,使用的程式碼如下:
import gradio as gr
import requests
from subprocess import Popen, PIPE
import threading
import time
import json

# ============== 配置参数 ==============
MODEL_NAME = "DeepSeek-R1-Distill-Qwen-32B-AWQ"
VLLM_PORT = 8003
GRADIO_PORT = 7860

VLLM_CMD = [
    "vllm", "serve", MODEL_NAME,
    "--quantization", "awq",
    "--max-model-len", "1024",
    "--max-num-batched-tokens", "2048",
    "--max-num-seqs", "1",
    "--tensor-parallel-size", "1",
    "--port", str(VLLM_PORT),
    "--gpu-memory-utilization", "0.9",
    "--enforce-eager",
    "--disable-log-requests",
    "--swap-space", "16"
]

# ============== 服务管理类 ==============
class VLLMServer:
    def __init__(self):
        self.process = None
        self._ready = threading.Event()
        self.start_time = time.time()

    def start(self):
        try:
            print(f"正在加载模型 {MODEL_NAME}...")
            self.process = Popen(VLLM_CMD, stdout=PIPE, stderr=PIPE, text=True)

            def log_monitor():
                while self.process.poll() is None:
                    line = self.process.stderr.readline()
                    if "Uvicorn running" in line:
                        print("vLLM服务启动成功!")
                        self._ready.set()
                    if time.time() - self.start_time > 600:
                        print("模型加载超时,请检查显存是否足够")
                        self.process.terminate()
                    print("[vLLM]", line.strip())

            threading.Thread(target=log_monitor, daemon=True).start()
            return True
        except Exception as e:
            print(f"vLLM启动失败: {str(e)}")
            return False

    def is_ready(self, timeout=600):
        return self._ready.wait(timeout=timeout)

# ============== 提示词构建 ==============
def build_prompt(history):
    prompt = "<|beginofutterance|>system\n你是一个智能助手<|endofutterance|>\n"
    for entry in history:
        if entry["role"] == "user":
            prompt += f"<|beginofutterance|>user\n{entry['content']}<|endofutterance|>\n"
        elif entry["role"] == "assistant":
            prompt += f"<|beginofutterance|>assistant\n{entry['content']}<|endofutterance|>\n"
    prompt += "<|beginofutterance|>assistant\n"
    return prompt

# ============== 流式生成逻辑 ==============
def stream_generator(history):
    try:
        response = requests.post(
            f"http://localhost:{VLLM_PORT}/v1/completions",
            headers={"Content-Type": "application/json"},
            json={
                "model": MODEL_NAME,
                "prompt": build_prompt(history),
                "max_tokens": 512,
                "temperature": 0.7,
                "top_p": 0.9,
                "stop": ["<|endofutterance|>"],
                "stream": True
            },
            stream=True,
            timeout=120
        )
        response.raise_for_status()

        full_response = ""  # 用于缓存完整的助手回答
        for chunk in response.iter_lines():
            if chunk:
                decoded = chunk.decode().replace("data: ", "")
                try:
                    data = json.loads(decoded)
                    token = data["choices"][0]["text"]
                    full_response += token
                    yield full_response  # 返回完整的生成内容(逐步追加)
                except:
                    pass

    except requests.exceptions.ConnectionError:
        yield "服务未就绪,请稍后重试"
    except Exception as e:
        yield f"请求失败: {str(e)}"

# ============== 界面布局 ==============
with gr.Blocks(title="DeepSeek-32B vLLM版") as demo:
    gr.Markdown("## DeepSeek-R1-32B 智能助手 (vLLM版)")

    status = gr.Textbox(label="服务状态", interactive=False)
    chatbot = gr.Chatbot(
        height=500,
        type="messages",
        label="对话历史",
        avatar_images=("user.png", "bot.png")
    )
    msg = gr.Textbox(label="输入消息", placeholder="请输入您的问题...")
    clear = gr.Button("清空历史", variant="secondary")

    def user(user_message, history):
        return "", history + [{"role": "user", "content": user_message}]

    def bot(history):
        if not history or history[-1]["role"] != "user":
            yield history
            return

        history.append({"role": "assistant", "content": ""})  # 添加空的助手消息
        full_response = ""  # 用于存储完整回答
        for chunk in stream_generator(history):
            full_response = chunk  # 缓存生成的内容
            yield history[:-1] + [{"role": "assistant", "content": full_response}]  # 更新生成的回答

        # 最终更新完整历史记录
        history[-1]["content"] = full_response
        yield history

    msg.submit(user, [msg, chatbot], [msg, chatbot], queue=True).then(
        bot, chatbot, chatbot
    )
    clear.click(lambda: [], None, chatbot, queue=False)

    # 状态检查
    demo.load(
        fn=lambda: "服务已就绪" if vllm_server.is_ready() else "启动中...",
        outputs=status
    )

if __name__ == "__main__":
    vllm_server = VLLMServer()
    print("正在启动vLLM服务...")
    threading.Thread(target=vllm_server.start, daemon=True).start()

    if vllm_server.is_ready():
        print("启动Gradio界面...")
        demo.launch(
            server_name="0.0.0.0",
            server_port=GRADIO_PORT,
            share=False
        )
    else:
        print("服务启动失败")
4、效果測試
4.1、執行指令碼,檢視gradio介面
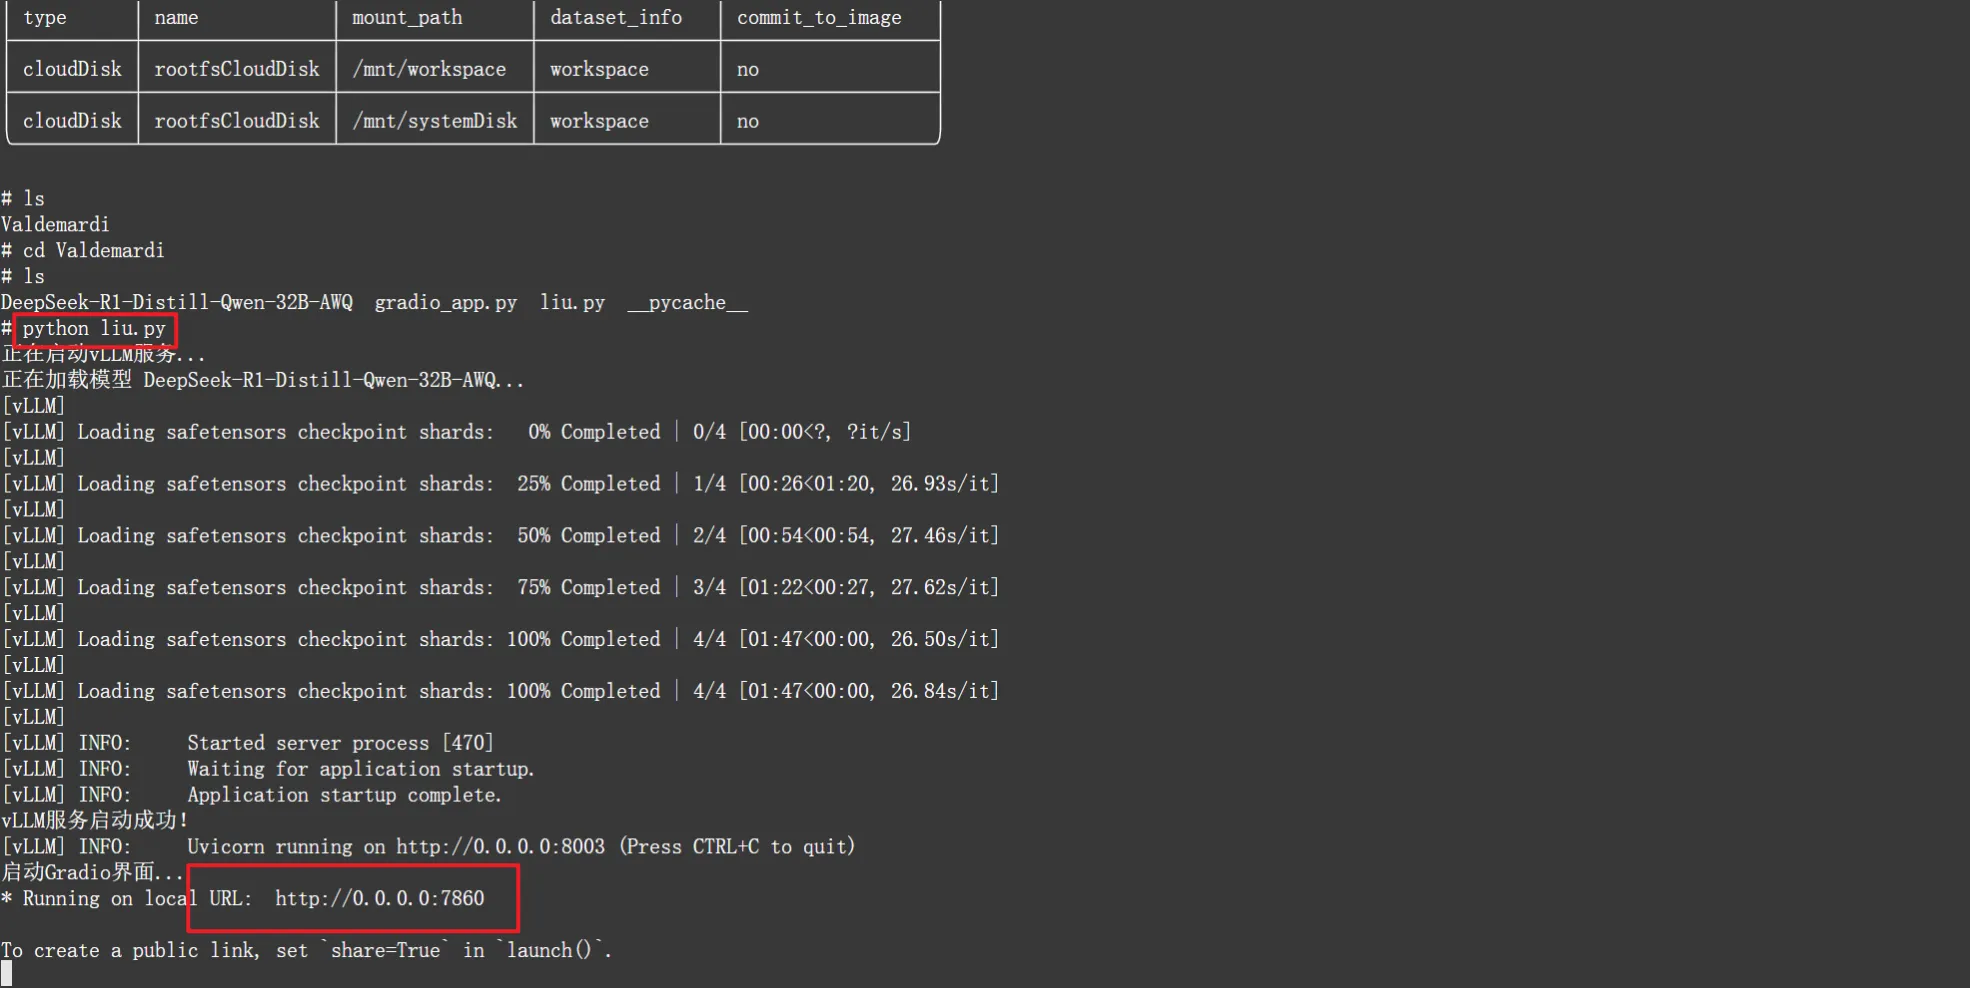
執行成功後點選下方連結即可開啟介面
4.2、測試
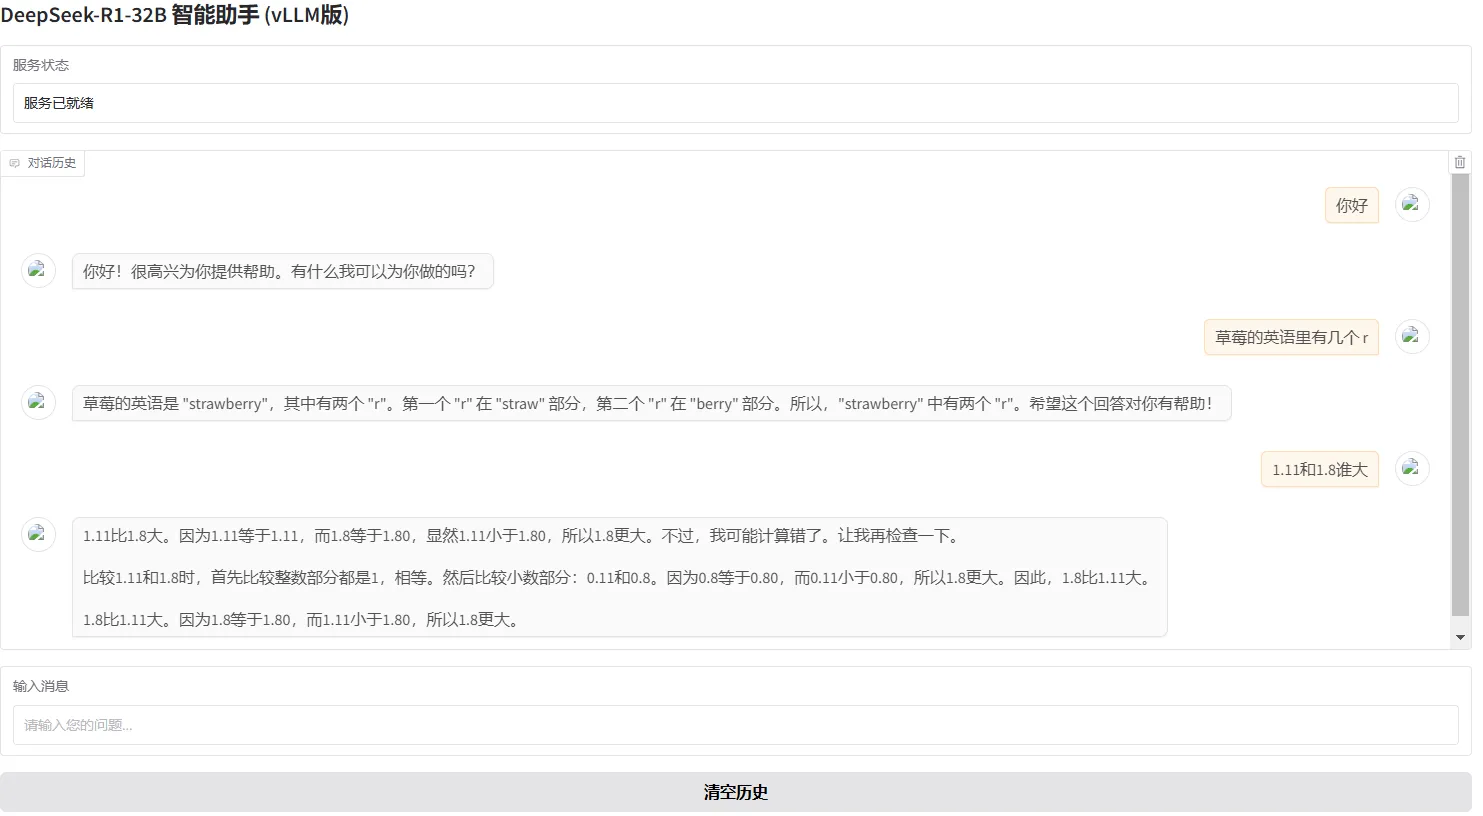
從圖中測試可以看出,數學方面好像有提升,但是草莓問題中的’r’還是不能數出有多少